Table, chart and layout extraction
Header and Footer Removal in Document Preprocessing
Removing headers and footers from documents can boost AI accuracy by 20 percentage points.
Margaret Solloway
Contributing Editor · · 10 min read
Removing headers and footers from documents can boost AI accuracy by 20 percentage points.
Fixed-size chunking outperforms semantic chunking on real-world benchmarks, despite its simplicity.
CommonForms dataset now benchmarks form field detection against vendor claims.
Modern tools combining OCR and vision models now extract chart data from PDFs as structured tables.
Metric choice and dataset quality reveal which models truly handle merged cells best.
Conversion missteps destroy table relationships before RAG systems even retrieve them.
Set your scanner to 300 DPI minimum, or OCR will fail no matter how smart your software is.
Document prep choices like font and layout matter far more than the OCR engine itself.
Enterprise OCR must handle bidirectional text and mixed scripts in the extraction layer itself.
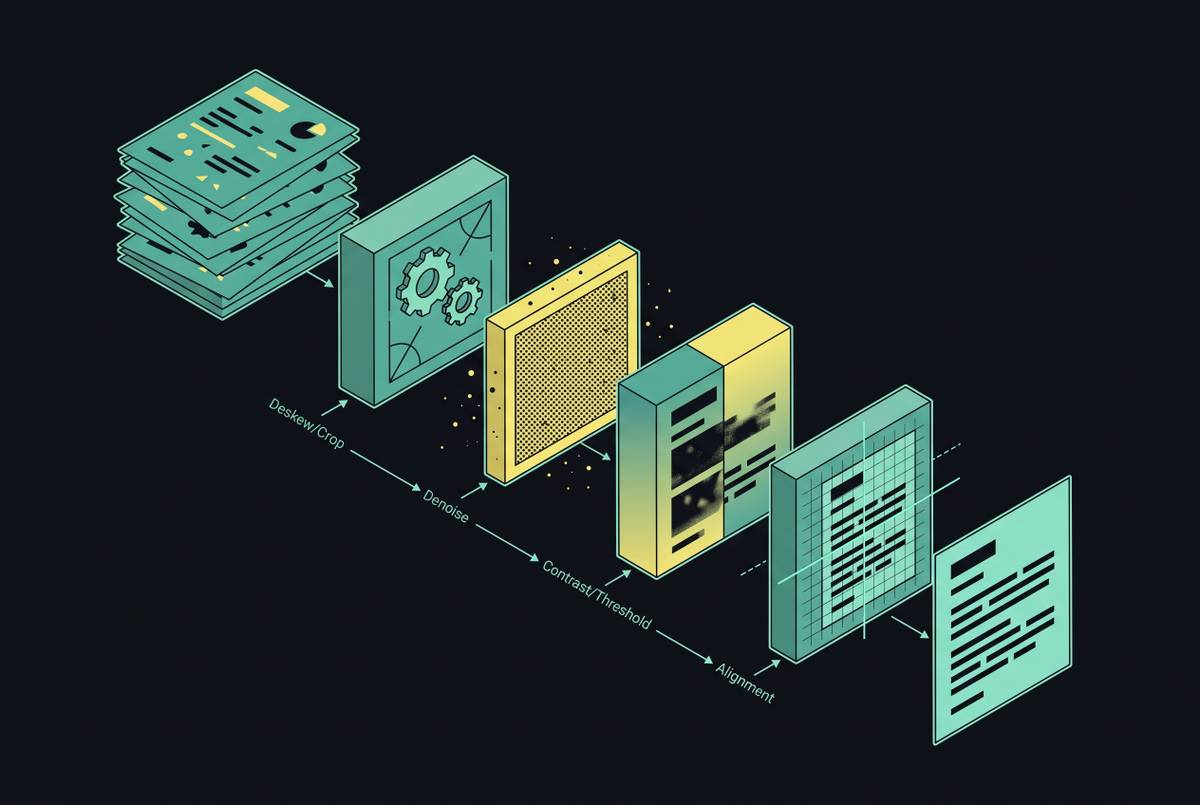
Sequence matters: preprocessing steps in the wrong order leave OCR stuck between broken and working.
Document quality matters more than model selection for improving real-world handwriting recognition.
Vendor benchmarks measure clean text, not the dense PDFs that break OCR in practice.