Human-in-the-Loop Annotation Quality Control for Document AI
Layered human checks catch silent model failures that confidence scores alone cannot detect.
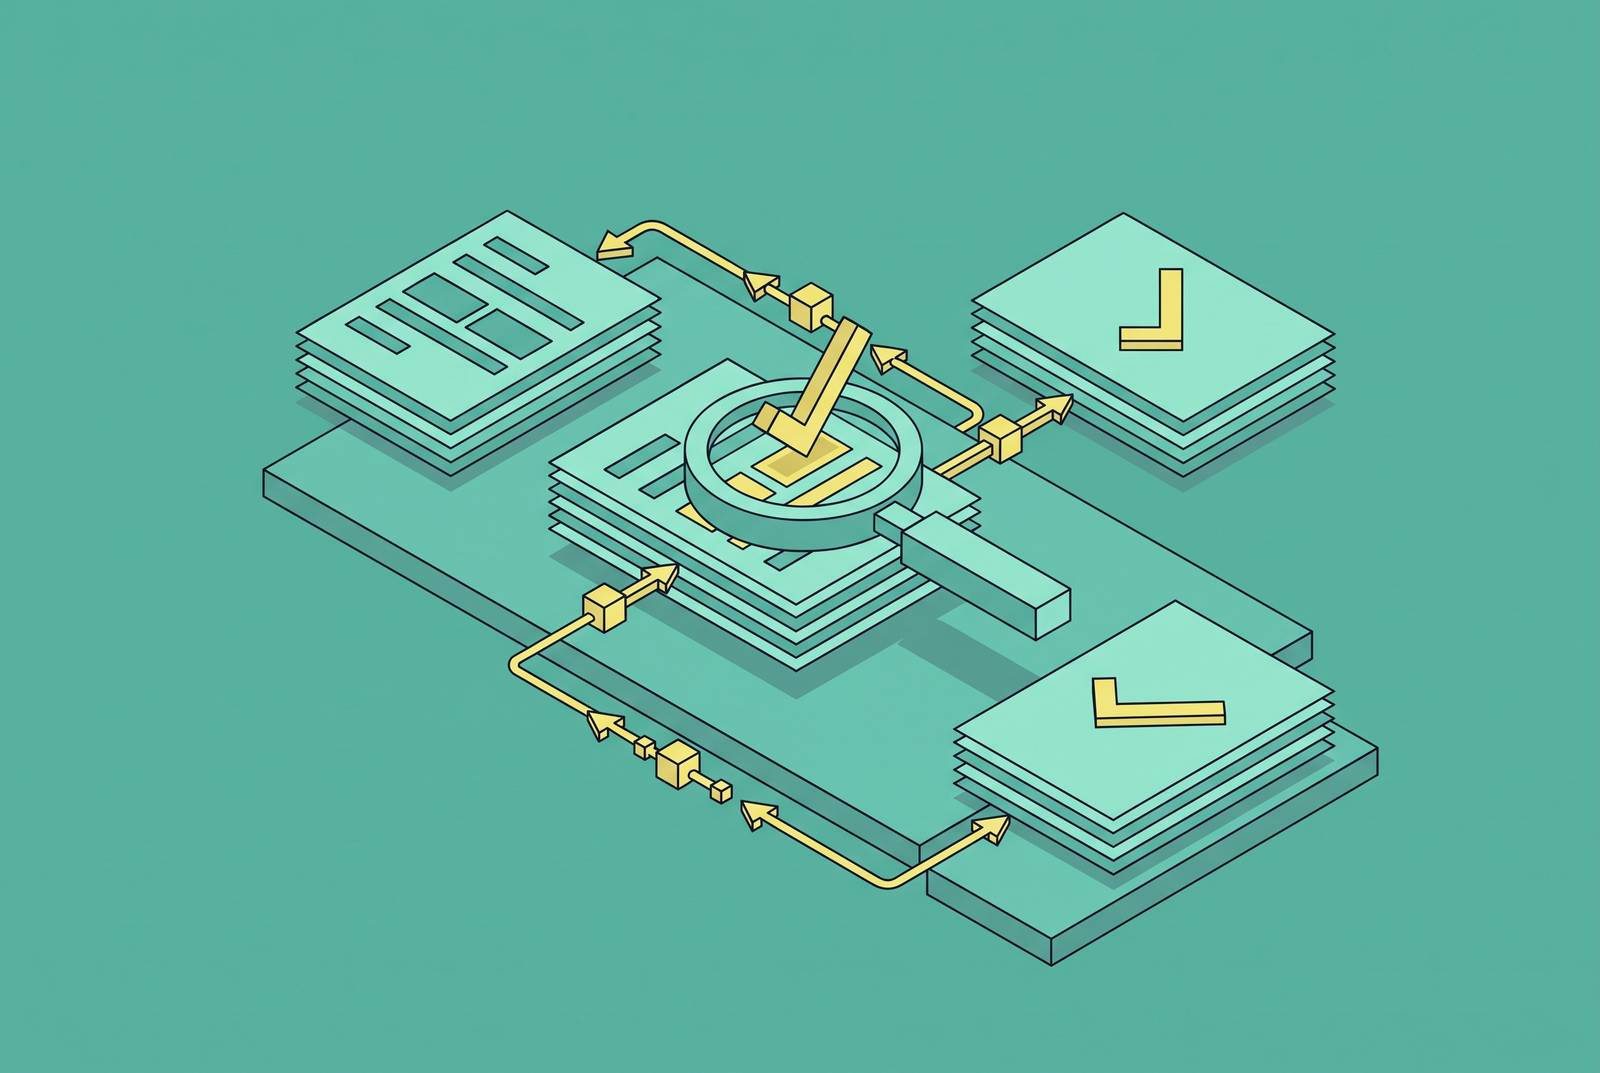
A document AI pipeline used on invoices and contracts may look sound across every dashboard metric, including throughput, latency, and completion rate, even as it keeps assigning the wrong label to a rare field week after week. This article explains how to catch those failures with an architecture of layered human oversight, where confidence-based triage, competing model outputs, and continuous feedback replace a lone review gate tacked onto an end-to-end automated workflow.
Why Document AI pipelines fail silently
A pipeline lacking a review gate will continue operating through its own errors, since no mechanism prompts it to pause and verify. Each incorrect label enters the training set as though valid, so the subsequent version absorbs those mistakes together with its accurate lessons. No alarm sounds at this stage, throughput does not dip, and no error message appears. Outputs continue flowing at an unchanged pace and with identical certainty, keeping the drift concealed until a downstream failure such as a rejected compliance filing or misrouted payment or missed clause compels investigators to trace the model's entire history.
Human-in-the-loop AI typically refers to a machine learning method in which people weigh in at crucial stages, such as when a model is being trained, when its outputs are checked, or when a final call is made, specifically to sharpen model performance and reduce errors. Without such checkpoints, a mistake goes unnoticed. A model may be certain yet mistaken, scoring an outright wrong result as highly reliable, and a pipeline that lacks a review gate cannot distinguish confident results from correct ones. Labels produced by an LLM pose that danger in another form: such a model may invent details absent from the underlying text or badly misread how it is organized, and having a second LLM pass judgment is no substitute for a person doing the review. At best, it functions as a baseline supporting human oversight or an addition to human oversight, since it inherits the identical limitations of the initial system and often overlooks the majority of errors that people would identify. In fields like medical diagnosis, financial oversight, and legal analysis, the stakes are too high for either people or machines to catch every critical issue on their own. For this reason, intentional integration of both approaches becomes necessary instead of hoping their coverage will naturally intersect.
Where annotation errors come from in document workflows
Annotation errors don’t just pop up randomly. Recognizing those recurring tendencies matters when designing detection tools. So Document AI quality assurance must target those recurring tendencies rather than attempting a blanket reduction in variance.
When annotators grow tired, they fall back on spatial cues, labeling a field by its location rather than reading its content, since placement offers a quicker shortcut than careful verification. Unclear instructions present another distinct issue, unlike cases where the source material simply omits the required details. In such cases, the instructions fail to equip the reviewer with what is needed to identify the right tag, despite the source text containing the answer. A third factor is subjectivity, which proves most problematic during reviews of legal or clinical material, since two skilled annotators examining identical text may reach divergent conclusions when personal perspective shapes the judgment equally with the words themselves.
Of the four sources, the last one is the hardest to spot and the most critical to grasp when planning a human review stage: automation bias from LLM pre-labeling. Exposing reviewers to machine-generated tags ahead of independent evaluation inflates how certain they feel about their choices. Schroeder et al. documented this in ACL 2025, showing that crowdworkers relied strongly on LLM suggestions due to the combined pull of automation bias and anchoring bias. The safeguard meant to detect algorithmic errors ends up adopting them. Rather than acting independently, these four failure modes amplify one another: tired reviewers exposed to machine-generated suggestions are twice as likely to approve incorrect labels uncritically, since exhaustion saps their motivation to verify while the automated tag supplies a convenient reason not to. Reliable datasets demand that gold standards, guidelines vetted by experts, consensus mechanisms alongside annotation traceability plus multi-step validation function together, each element designed to neutralize a specific vulnerability from the four outlined above.
What confidence-based routing works and cannot do alone
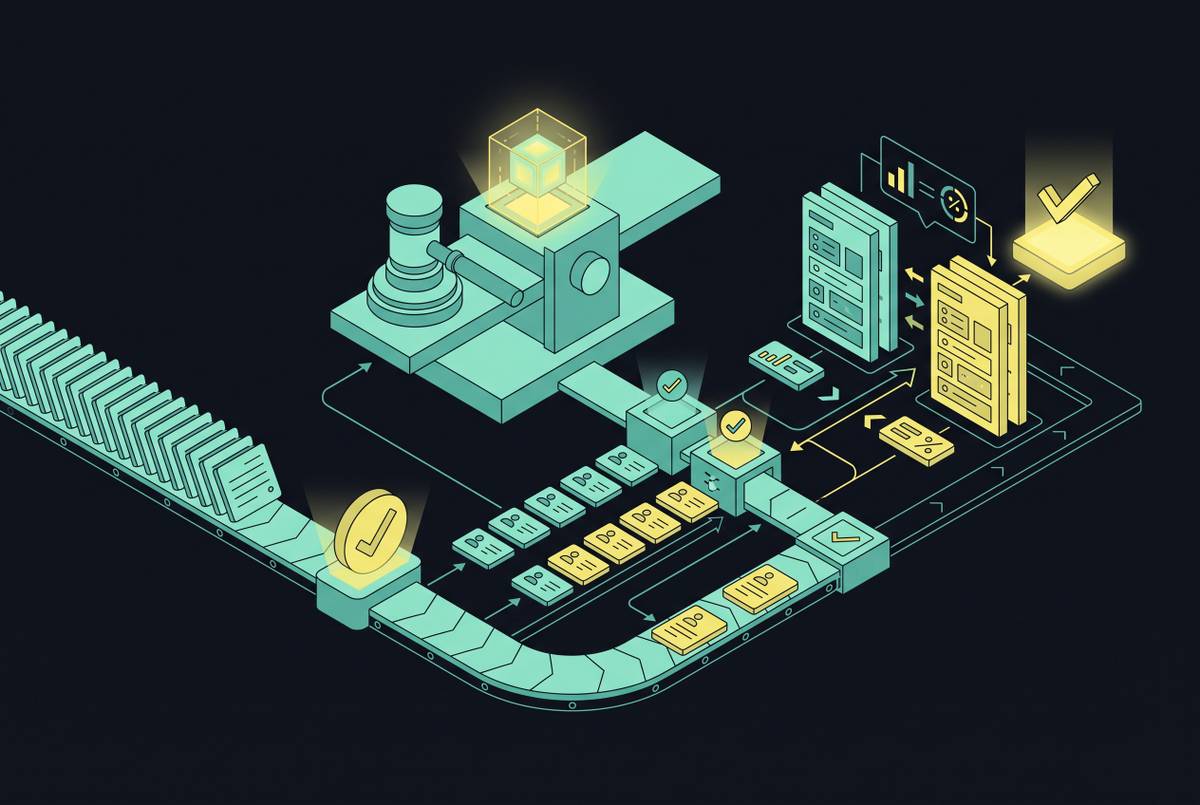
Most human-in-the-loop document workflows begin with confidence-based routing, a simple decision method. The system uses a cutoff to separate items it can handle alone from those requiring human labeling: higher-scored predictions are accepted automatically, and lower-scored ones are routed for review. In a standard document setup, the AI pulls data out of invoices, contracts, and similar files, lets high-confidence entries proceed, and sends low-confidence entries, unclear handwriting, dense tables, or ambiguous date formats to reviewers. Those reviewer fixes are then folded into the workflow so it performs better later. This keeps manual workload far lower than full human inspection and focuses reviewers on cases the model has already flagged as uncertain.
The problem lies in what a confidence score does and doesn't reveal. Confidence routing is designed to flag uncertainty, not errors the model commits while fully convinced of itself; that gap is the core argument for making a layered system mandatory instead of optional. Confidence scores can go wrong in ways built into the model rather than cropping up now and then: one model may rate highly an invented field value, a layout it repeatedly misreads, or a type of mistake it reproduces identically each time. Not one of them is sent for review, since escalation happens only when the system senses its own doubt, and each of these is an instance of being certain while wrong. Post-processing review is there precisely for this kind of failure, the hallucinations, wrongly read context, repeating bias, because nothing in confidence routing would ever bring them to light by itself. So the natural follow-up is this: when confidence by itself cannot flag a model that is sure but mistaken, what other signal should prompt a person to take a look?
Using model disagreement as an escalation trigger, not just confidence
Rather than querying a single system about its certainty, check if two separate ones align. By leveraging architectural diversity to flag mismatches, this oversight tier detects flaws that certainty metrics are structurally blind to. A pair of unrelated architectures rarely err identically on a given attribute, unlike a lone network that can fail while projecting certainty.
Designed to pull structured data out of historical documents, the Double Triangle Annotation framework relies on a single premise: powerful models working separately will rarely make identical mistakes on identical fields. Two architecturally separate vision-language systems process every document simultaneously. If they match, the annotation passes without any human involvement. When they diverge, a human jury intervenes, shifting the reviewer's role away from generating initial annotations toward adjudicating disputed ones. An additional tier then compares two of these paired systems, forwarding any lingering disagreements to a domain expert. This layered approach ensures that costly specialist review is reserved solely for the most stubborn discrepancies.
Testing on the Guides Rosenwald corpus, which compiles French medical directories from 1887 through 1906, consensus automatically approved most of the 13,595 processed fields while yielding a final Word Error Rate of 0.003. The approach operates without bespoke tuning or prior assumptions about annotation distributions. Any structured extraction task pairing multiple models is a valid target, extending well beyond historical documents. The approach also strengthens alongside advancing base models: agreement levels rise, fewer fields require manual checking, and accuracy continues climbing, so the setup grows more capable over time instead of going obsolete. Although executing a pair of models rather than one raises computational expense, the system approved more than 85% of entries without any human involvement, and this drop in manual workload balances out the added processing burden while directing whatever labor is left toward the areas where it provides the greatest benefit.
Designing the human review queue to avoid introducing new errors
Selecting which cases enter review is only part of the problem. A poorly structured queue brings back the very problems review is meant to prevent, including anchoring, fatigue and subjective judgment, at the next stage of the workflow.
The automation bias risk noted earlier resurfaces at this stage with the gravest potential for harm. Exposing the pre-label or confidence score before an independent assessment causes reviewers to adopt the algorithm's conclusion, converting a corrective checkpoint into mere rubber-stamping. Interface choices must therefore govern the timing and sequence of revealing algorithmic outputs, rather than merely determining which items enter human evaluation. Forming an independent conclusion before viewing the algorithmic suggestion transforms the task entirely compared to treating that output as the baseline.
Without adjudication, disagreements would stall progress rather than remain useful. Whenever a single field receives conflicting tags from two annotators, an experienced reviewer or subject-matter specialist resolves the clash by establishing the definitive canonical label. Rather than merely correcting a single mistake, this process converts conflicting judgments into actionable insights that refine annotation instructions and reviewer preparation.
Golden questions offer a secondary yet valuable safeguard, woven through the workflow to confirm that reviewers remain focused. Such items carry definitive answers yet look exactly like ordinary assignments, preventing annotators from spotting the checks. This tackles a core motivation gap where lax oversight invites low effort, providing an evidence-based method to spot slacking before overall results suffer. Specialists should sit at the final escalation stage, handling only items that survive machine agreement and require human judgment, rather than diluting their focus across routine checks on all incoming work.
Closing the feedback loop so human corrections improve future routing
Keeping humans in the loop without ever closing it turns the process into a cost instead of an improvement mechanism. Teams may waste countless hours each month fixing identical errors, yet unless such feedback shifts a model threshold or fuels retraining, the system will continue producing those very flaws at an unchanged pace forever. All that effort yields no reduction in mistakes.
Operational closure begins with where corrections are kept. When a reviewer changes something, the reviewer's correction should become structured labeled data that training and evaluation jobs can use again, rather than a one-time log entry that is later ignored. Teams should repeatedly examine escalation patterns: when the same document type or field class keeps reaching a person for review, that class's threshold should change, rather than adjusting one broad threshold that handles every field alike. Modern labeling pipelines handle this through steady watching of live production work plus checks across successive stages, a running cycle rather than one retraining pass treated as done.
Consensus between labelers offers a helpful indicator, yet matching answers do not guarantee accuracy, because both reviewers might share the same mistake. The true benefit surfaces after conflicting judgments, when an arbiter assigns a definitive tag to realign the model alongside future labelers. When adjudicators repeatedly settle identical disputes in one manner, that pattern should be codified into the guidelines so recurring uncertainties no longer trigger new reviews. Tools showing reviewers uncertainty at the instance level let them focus on low-confidence items rather than sampling uniformly, equipping this cycle with necessary instrumentation, while traceable annotations remain essential to ensure data quality. Completing this cycle makes the system cheaper to run precisely while boosting accuracy: once the model masters previously escalated categories, fewer items need review, leaving only truly novel or difficult cases that continue enriching future training rounds.
How the three layers interact as a system
Reliable document AI demands that confidence routing, escalation triggered by disagreement, and feedback loops operating in a closed cycle be engineered for mutual dependence. Adjusting one component in isolation, leaving the rest broken, merely offers illusory mastery, since glowing status screens often mask pipelines failing precisely as outlined earlier.
Confidence routing determines which items reach a human before anything else. When calibration is off, easy cases that never required human attention overflow the review queue, or the truly difficult ones that someone should have examined never arrive. Escalation triggered by disagreement targets the blind spot built into confidence routing: mistakes the model holds with complete certainty. Absent this safeguard, the feedback loop learns from data that leaves out a whole category of model errors. Easy cases get better through the loop, but confident blind spots stay exactly as they were. Lacking that circular feedback, the remaining two layers stagnate: flagged mistakes cycle through review endlessly because caught issues never alter the underlying model or its threshold. All three components rely on one another, meaning success in just a single stage reproduces the same failure seen in fully automated setups. The breakdown goes unnoticed until the expense emerges in another area.
Sources
- Double Triangle Annotation: A Scalable Human-in-the-Loop Framework for High-Precision Historical Document Annotation
- Incentivizing High-Quality Human Annotations with Golden Questions
- Human-in-the-Loop Artificial Intelligence: A Systematic Review of Concepts, Methods, and Applications
- Beyond Consensus: Perspectivist Modeling and Evaluation of Annotator Disagreement in NLP