End-to-End Accuracy Measurement Across Document Ingestion Pipelines
Measuring accuracy at each pipeline stage reveals errors hidden by aggregate scores.
Even when a document ingestion pipeline reports impressive precision upon completion, severe breakdowns may persist unnoticed because that lone metric obscures the actual fault. When retrieval degrades, teams usually look at the model first since it delivers the answer everyone sees. Yet feeding an LLM damaged or wrongly tagged text simply yields polished, assured output built on those same errors. Basic RAG setups fail to fetch the right context about 40% of occasions, prompting the LLM to produce polished but unfounded replies anchored in irrelevant sources. Such a failure mode traces back to how documents enter the system instead of implicating how the LLM reasons.
The reason a single pipeline score misleads is structural. Accuracy in a multi-stage pipeline compounds rather than averages: an error introduced at parsing does not stay at parsing. It travels into chunking, then into embedding, then into whatever retrieval or extraction layer sits downstream, and at each stage it has the chance to combine with new errors rather than simply persist. Root-cause attribution becomes difficult precisely because the only thing being measured is the final output, which reflects every stage's errors blended together with no way to separate them.
Partial correctness is the form of this that poses the greatest danger. A document may score well on field accuracy overall, yet its mistakes land precisely in the fields of greatest structural weight: section headers, dates, entity references, the ones that retrieval indexing and chunk boundary logic rest on. The log for the pipeline will record a score that passes. Weeks later, that same error resurfaces as a retrieval failure, its origin obscured by each intermediate stage lying between the flawed extraction and the flawed answer. This gap stays hidden under aggregate scoring, which was never designed to distinguish the failure itself from the point where it arose. Untangling that distinction is the very reason this article takes the shape it does.
The four distinct accuracy layers that a single pipeline score collapses into one misleading number
That means spelling out exactly which things deserve separate measurement. Most pipelines blur four separate layers of measurement, each behaving and failing on its own. A green result on any single layer says nothing trustworthy about what sits above or below.
The base layer gauges how faithfully OCR captured the page, measuring accuracy at the level of individual characters or tokens. As the foundation of the stack, this signal frequently stays strong even when downstream extraction is collapsing, since OCR might capture every character on a page yet still deliver the wrong structure to a system that matches against a schema. Next comes accuracy at the field level: did the right value land in the right schema field, usually captured with F1 scores per field that balance precision and recall across individual data items. At the document level, the strictest tier, one incorrect field dooms the entire document regardless of how impressive the F1 score for that individual field appears. This is the tier practitioners watch most closely, and the toughest one to instrument directly.
The mismatch shows up in real systems as well as in theory. Researchers examining 153 digitized hospital lab reports found OCR text detection scoring 0.93, but the later step for pulling out test names and values, including named entities, reached only about 0.86. A single rolled-up metric would hide this layer-to-layer drop, reducing two sharply different outcomes to one figure. Structured-output evaluations show a similar split: systems may often emit well-formed JSON, while document-level accuracy checks approve only a small share of those results. Well-formed output does not guarantee accurate content, and if a pipeline stops at JSON validity, faulty JSON can still slip through.
How parsing failures propagate: three mechanisms that carry errors downstream
Explaining why these levels split apart calls for a causal account of how faults travel along a pipeline's stages, not merely a map of where they get measured. Three separate mechanisms push silent errors onward from parsing to chunking, then embedding, then retrieval, yet none shows up when only final output is watched.
The initial failure mode comes from large-scale variation in document formats. In live systems, vendor invoices adopt different layouts, contracts follow local rules, and PDF scans may carry tilted text layers, disrupting OCR alignment. A parser calibrated to a single supplier's invoice pattern can assign values to the wrong fields after encountering a new supplier format, leaving damaged chunk metadata while parsing reports no error. There is no loud failure. The process continues, carrying the bad data inside fields that appear filled but are not.
A second failure mode is quiet data damage caused by ingestion drift. As new batches arrive in different layouts, the parser may apply an outdated schema, scrambling dates, entity links, and headings in one pass while the retrieval index silently incorporates the bad data. Even deployment-grade RAG that passed its launch audit can decay in just a few months without any code release, because later inputs no longer match the extractor’s training assumptions.
Chunking serves as the third mechanism, amplifying problems rather than remaining neutral. By dividing content into blocks of predetermined length, this approach disregards the natural boundaries of thoughts, paragraphs, and structural divisions. Splitting inside a paragraph breaks the link connecting an assertion to its supporting proof, so retrieval returns an isolated piece lacking the nearby text required for comprehension.
The three mechanisms do not just add up, they build on one another. When layout misclassifies a field, it damages metadata for material already split across a chunk boundary, so the embedding model records the resulting confused, misnamed segment in the vector index. Any downstream query that reaches that embedding takes on all three errors together, and no log shows them one by one. A breakdown anywhere in the pipeline spreads into the steps after it; treating a stage as skippable leaves gaps that later show up as runtime agent errors, consistent with the earlier finding that retrieval failed about 40% of the time and often hiding where the problem began. Afterward, tracing that failure to its origin is hard precisely because the way it moved downstream wiped out the lines between mechanisms.
What current benchmarks reveal about where accuracy degrades across document types and schema complexity
Empirically, the way a benchmark is built confirms the propagation model, and benchmarks expose failure at whichever pipeline stage they measure.
The primary leaderboard for evaluating full-document parsing, OmniDocBench debuted at CVPR 2025. The benchmark simultaneously evaluates reading order, table structure via TEDS, formula recognition via CDM, and text edit distance. By mid-2026, TeleOCR leads OmniDocBench among purpose-built vision-language systems at 96.91 overall, with OvisOCR2 scoring 96.47 plus PaddleOCR-VL-1.6 reaching 96.34, while the broadly capable Gemini 3 Pro hits 92.91. Such scores reflect how well each system handles document parsing.
ExtractBench, published on arXiv as 2607.29677 and evaluated in June and July of 2026, measures a different layer entirely. It covers thousands of pages across hundreds of documents spanning eight business domains and 67 document types, scoring accuracy, completeness, grounding, and cost together. On its live leaderboard as of October 2026, LlamaExtract Agentic Plus leads at 95.9 overall F1, with Pulse (Effort) also at 95.9 and LlamaExtract Agentic at 94.8. The informative part of ExtractBench is the pattern it reveals: commercial vision-language models perform well on short documents but often truncate record lists on longer ones, while coding agents hold accuracy steady at much higher cost. Document length behaves as an error-amplifying variable in its own right, a finding that aligns directly with the compounding mechanisms described above, since longer documents give format variance and chunking failures more surface area to act on.
Schema breadth shows this most clearly. The ExtractBench v1 study revealed that as schema width grew, frontier models saw accuracy plummet, with every one producing 0% valid output across a financial reporting schema containing 369 fields. A benchmark restricted to narrow, uncomplicated structures would never reveal such a cliff. OmniDocBench paired with ExtractBench proves this from both angles: parsing evaluations may hit near-97 yet reveal nothing regarding extraction, just as extraction tests might yield strong F1 for brief texts yet mask total failure across lengthy documents or broad schemas.
Schema Drift as a Continuous Monitoring Problem
Benchmarks show only a snapshot. In production, pipelines keep running over time, so the ingestion-drift dynamics discussed above keep evolving after deployment. As inputs evolve through new fields, renamed concepts, or revised layouts, teams need continuous evaluation to catch accuracy loss soon enough to refresh models or adjust rules before mistakes pile up across many documents.
This failure pattern looks just like ingestion drift, only stretched across time instead of spread across document types processed at once. A parser calibrated for one supplier's billing layout performs fine until that supplier redesigns its itemized rows, after which it quietly misclassifies without triggering any error in the system. The deployment stayed exactly the same. What shifted was the input distribution.
Measurement becomes an ongoing lifecycle concern instead of a single certification event. A group verifying precision at launch and subsequently tracking just overall output metrics misses schema drift until it surfaces as retrieval breakdowns later, when many records have entered the system holding faulty metadata undetected in the index. Scoring confidence at the individual field level offers a workable way to spot trouble sooner, since it reveals the accuracy shortfall hidden behind a strong overall number, points to the exact fields where extraction is least certain, and operates on an ongoing basis instead of waiting for planned review checkpoints.
One way to address this problem is MADP, whose PFTFI, Prompt Fine Tuning through Feedback Inheritance, folds in human corrections to adjust extraction gradually while leaving the models unretrained, keeping the pipeline aligned as document layouts change. Its value is not the feature itself but the pattern it points to: teams need steady, step-by-step correction to match drift that happens the same way.
Per-stage instrumentation as the practical architecture for catching errors before they compound
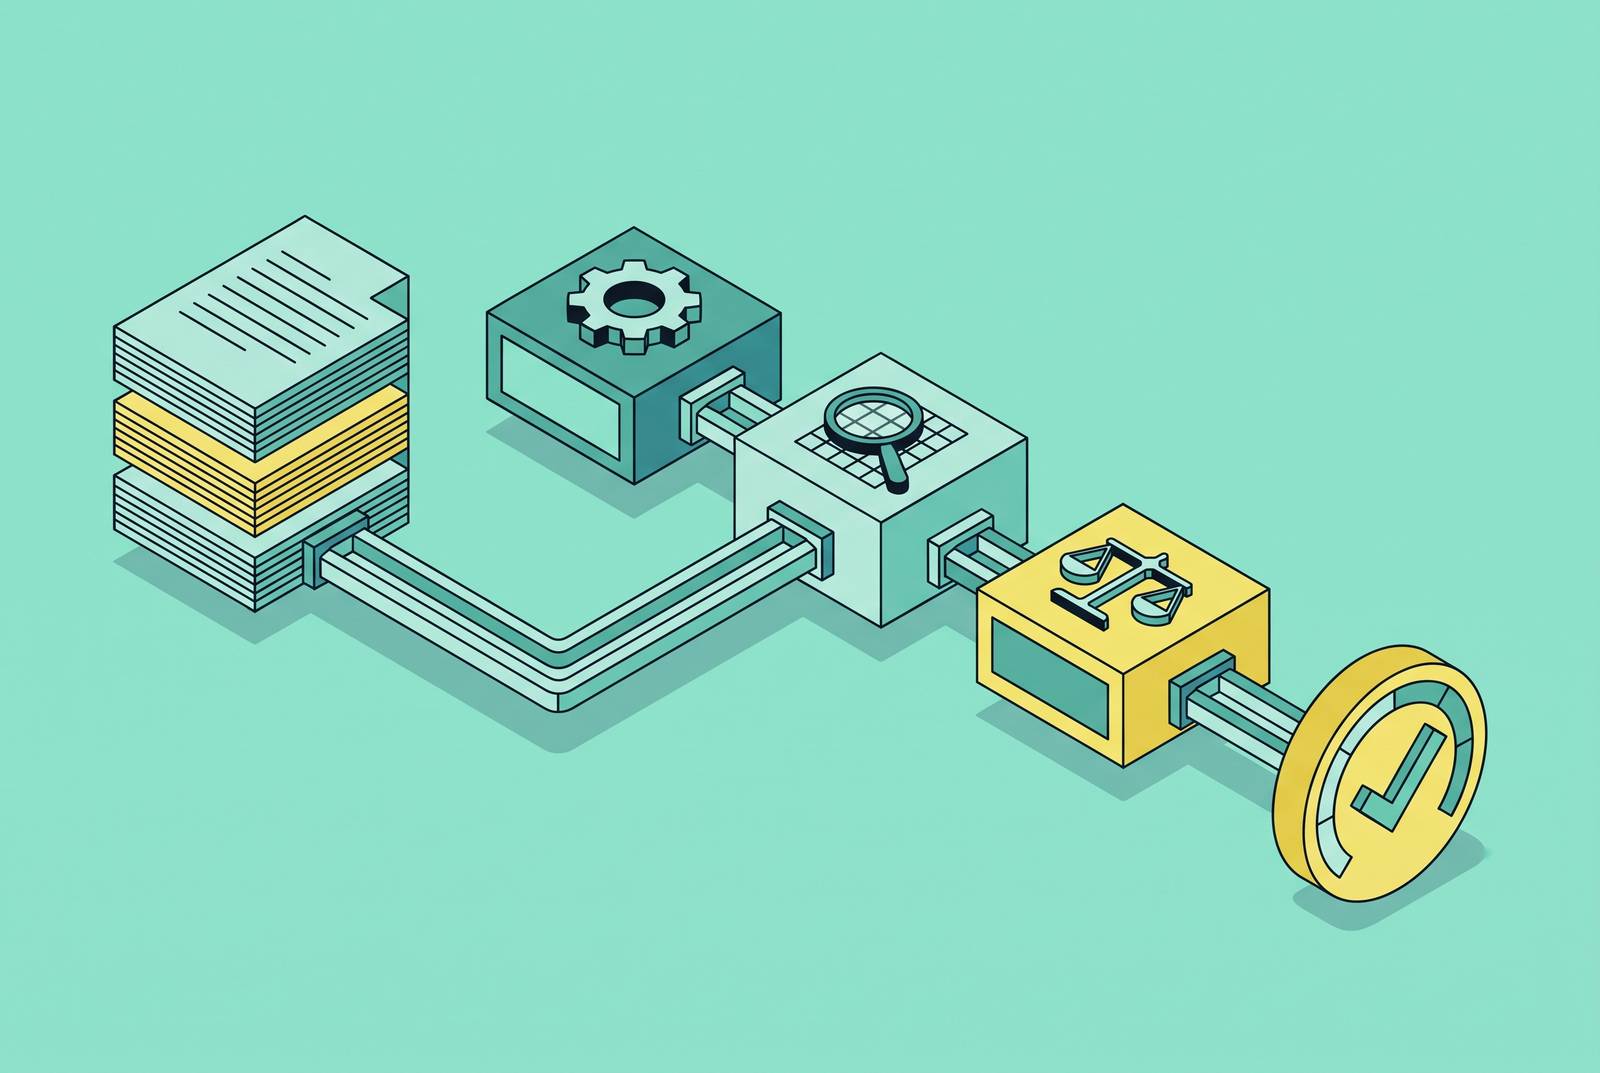
Measure each stage on its own rather than depending on a single top-line signal, since rolled-up pipeline figures mask the choke point, but per-stage timing, completion rates, and failure counts reveal exactly where it sits, so five distinct steps call for their own instrumentation.
Validate the parse before anything else. This step checks that the page geometry, content sequence, and tables have been reconstructed reliably before the output is sent to extraction logic. When a parser error slips through to extraction, it can populate fields incorrectly without triggering any extractor-side warning, because that layer cannot tell that the input was already wrong.
Confidence scores for individual fields are generated right during extraction. By highlighting uncertain fields, it allows you to steer choices before bad data reaches chunk metadata. Such scoring exposes incomplete accuracy rather than hiding it inside a single F1 metric, the typical outcome of relying solely on whole-document pass rates.
When the text is divided, this approach looks for cues like headings, paragraph breaks, and shifts in subject matter, letting each chunk follow the document's own organization instead of a rigid token limit. That resolves the amplification concern noted earlier, because a chunk built around meaning keeps each claim together with its supporting evidence rather than severing them the way an arbitrary token boundary can.
Schema contract validation occurs across three stages, namely post-parse plus post-extract alongside the final handoff check, where confidence thresholds route any low-scoring fields toward human review before they hit a downstream system. This triple-layer approach is essential because every phase isolates a unique error type: structural drift early on, labeling mistakes during extraction, and whatever blend persists into the final gate.
This instrumentation set also needs a fifth dimension, one that older pipelines often leave out altogether, which is grounding. ExtractBench pairs value F1 with grounding scores at both the word and page levels, so claims about accuracy must also show that the system points to the source location for each reported value. Source traceability is a measurable accuracy dimension by itself, not just a compliance checkbox added later.
Human-in-the-loop routing as the correction mechanism when per-stage instrumentation surfaces low-confidence fields
Once any stage of the pipeline marks a field as uncertain, that signal demands a response, and the evidence points to human review routing as the most reliable corrective. Sending flagged fields to reviewers, even when only a small share of documents is affected, raises overall extraction accuracy across document types as high as 99.2%.
Deploying MADP in production concretely demonstrates the model, processing 955 actual documents by January 2026. The pipeline relies on human oversight plus five dedicated agents, namely Classificator, Splitter, Parser, Extraction along with Validator, to achieve strong end-to-end automation rates. Testing a portion of the documents revealed that MADP in its complete configuration, guided by HITL oversight, reached robust accuracy at the document level.
The real drawback is that this approach can be expensive and slow, so teams should treat it as real rather than waved away. ExtractBench shows a tradeoff: top-performing systems charge 8 to 35 cents for each page, while no-metered-fee open-source options falter on lengthy files and more intricate schemas. Putting reviewers in the workflow also increases both delay and per-item expense beyond what the extraction step already costs.
The answer to that objection is to apply human review only where it is needed. At production scale, sending every document to a human would be too slow and too costly. Measuring each stage of the pipeline separately is what makes this possible. Without field-level confidence scores, a team cannot aim its review queue at the mistakes that actually carry weight, so it either reviews everything at a cost that breaks the budget, or reviews nothing and allows the compounding problems described in this piece to run from parsing all the way to retrieval.