Validation and Exception Handling in Automated Document Processing for Insurance
For insurers, paperwork remains the engine, whether delivered by PDF, fax transmission, or uploaded scan. Every day, thousands of policy packets, standardized ACORD paperwork, claim histories, clinical files, certificates of insurance, and FNOL submissions arrive through email, portal uploads, or scanning, each in its own layout. One carrier’s loss run may look nothing like another carrier’s version. A medical record from last month may be structured nothing like one filed a decade ago. They are the operating substance of the insurer, captured in whatever form the sender chose.
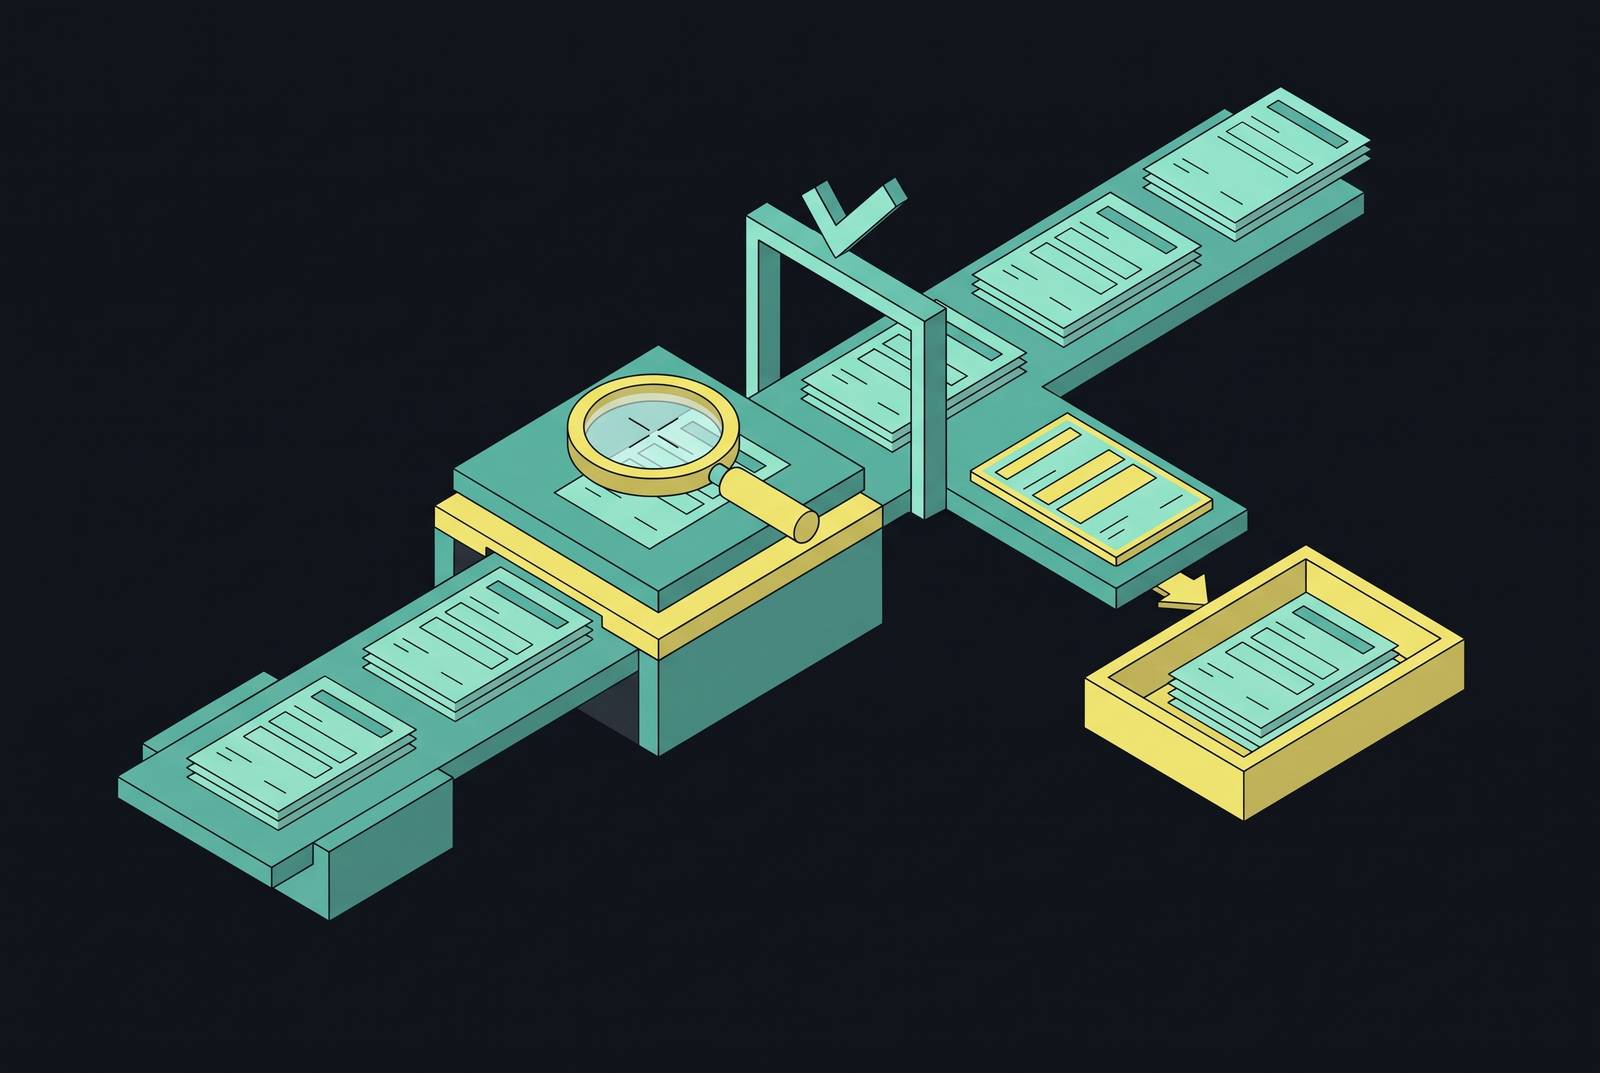
This work is foundational rather than peripheral because of the sequence triggered by a document's arrival. Infrrd's 2026 guide to straight-through processing explicitly maps this chain, showing how information must pass through ingestion, extraction, validation, and rules application before any transaction resolves. Each phase relies on its predecessor. A mistake at ingestion does not stay there. Such a flaw propagates through extraction and validation before reaching the rules engine's decision point, surfacing only at the end as something unrecognizable from its true origin.
So Infrrd defines STP in exactly those terms, as automation running the whole way through instead of at one point in the process, with a strong STP rate no longer merely desirable. It has become the minimum any competitor needs, since any workload that does not clear end to end carries a cost somewhere, whether in hours adjusters spend, scrutiny from underwriters, or delays a client feels while waiting on a decision. But none of that work can happen before the system reads the files coming into the pipeline correctly. Everything that follows, from rates computed to claims settled to policies issued, depends on the system getting the document right at the start. Document processing is thus the foundation on which every other piece of insurance automation rests.
What extraction alone cannot guarantee
Extraction settles what a document says, but it leaves open whether those details are accurate, up to date, or tied to the correct record. Pulling an identifier from a digitized form amounts to nothing more than parsing. Verifying that identifier against the authoritative database to ensure it matches the claimant is an entirely separate job, and blurring these two steps causes many automation initiatives to silently collapse.
In its claims automation guide, Neutrinos' therefore separates extraction from validation. The extracted fields must then be verified against policy data, outside databases, or any other source able to substantiate them, while identifying not-in-good-order documents, known in the industry as NIGO, remains a distinct step of its own. Even flawless parsing does not guarantee the document will pass validation.
The same problem also takes a subtler form. Even a document that clears classification and parsing without error can still yield a case decided incorrectly when the eligibility rules, the notes from clinicians, the codes for procedures, or the attachments it requires are incomplete. A document that parses cleanly is not automatically one an insurer can decide on, and nowhere is that distinction more apparent than in health insurance workflows. Datagrid's handling of medical records brings optical character recognition together with language models versed in medical terminology, yet that pairing only pulls the data off the page. Beyond that extraction step, the system must keep audit trails for compliance intact and give an underwriter the surrounding context needed to act on the data. Accurate reading and grasping what a document means for the decision are distinct duties; a tool that masters only the former has not completed its work.
Validation logic's role in catching extraction errors
This is the part of the process where the pipeline audits what it has already done, and the simplest form of that audit is spotting duplicates. When a single claim arrives twice, once via a portal and once as an email attachment, for instance, and no safeguard is in place, the system can treat them as distinct claims, producing duplicate payouts or competing case files that have to be reconciled manually. Flagging that collision ahead of duplication is a core validation step, not a nice-to-have.
Validation has to face outward as well as inward. Datagrid and Neutrinos both place enrichment within the validation layer: rather than merely confirming that a document holds together, the system resolves extracted values by consulting reference sources from outside parties. A policy number is verified against the authoritative record system. A provider identifier is verified in a registry. This layer exists to make sure a document's assertions agree with what independent sources say, and the lookup must be completed before any case can move forward.
None of this stays intact, though, unless a shared data model underpins intake alongside validation and adjudication. The architectural logic is clear in Neutrinos: drawing on a single model across all three stages means no document needs rekeying after its first capture, and any case marked as an exception arrives at review with its complete history intact. Lacking such a unified foundation turns validation into a pipeline-stalling checkpoint, forcing data to be re-entered with every pass. This distinction is crucial, shaping the path forward whenever a submission does not clear validation and must be routed elsewhere. Exception handling is that "somewhere", and its quality hinges wholly on what validation passes along.
Why routing alone is not enough for exception handling
Validation's role wraps up the instant a case trips a guard, whether that guard is for completeness, a policy rule, a duplicate screen, or business validation. That's where exception handling picks up, and it carries more decisions than most pipelines acknowledge. The system must figure out which exception is sent where, with what supporting information, and at what urgency, every one of which is a design decision on its own.
Neutrinos spells out its view of proper exception handling: the adjuster's starting point ought to be a choice, not a reconstruction job. When an exception shows up as an unorganized stack of files, the reviewer must first rebuild all the context the platform had already captured before any real assessment can start. If the exception instead comes through with its whole backstory already put together, the reviewer can jump straight to the real decision.
Most pipelines use confidence thresholds to pick which items get escalated. Infrrd illustrates this by sending low-scoring items to people for review while letting high-scoring ones proceed automatically. Deciding where to set that boundary involves genuine trade-offs with significant downstream effects. Infrrd further notes that certain files demand human eyes regardless of their score, including intricate or expensive claims with shifting factors, suspicious activity hinting at fraud, regulatory matters needing official checks, atypical situations beyond standard ranges, and underwriting choices requiring discernment over math. Such scenarios are neither uncommon nor appended later as a secondary concern. Instead, Infrrd builds its architecture from day one to handle these situations as a planned, routine class of work.
The deeper need is for exception handling to sort different kinds of failure. A missing field cannot be treated the same as conflicting policy terms, and neither is the same as a clue that fraud may be involved. Putting all three in a single reviewer path collapses the distinctions the validation layer made, and wastes the specificity validation created. Another case sits outside routing: a document may be valid and correctly tied to policy terms, yet still not support a decision when key medical notes, billing codes, or mandatory addenda are absent. The exception handling rules need a distinct label for "this file is valid but incomplete," treating that outcome separately from a mere referral to a person, "this file needs a human." If a pipeline cannot mark that difference, it has not actually implemented exception handling. It has merely extended the line.
Exception handling failure at scale: the CMS WISeR case
The most thoroughly recorded instance of exception handling collapsing at production scale involved a Medicare program instead of an insurance carrier, yet the breakdown mirrored the pattern outlined above. Launched in January 2026, the CMS WISeR model (Wasteful and Inappropriate Service Reduction) began using AI to make prior authorization decisions for Medicare beneficiaries across six states. Because contracted private firms applied AI to assess those requests, WISeR offers the most transparent example of exception handling failures at institutional volume.
These breakdowns were neither isolated nor minor. Coverage of the initiative showed that across its opening quarter, the pair of contractors rejected prior authorization requests numbering in the thousands. Virtix alone rejected more prior authorization requests than it authorized, prompting CMS to require a corrective action plan when the vendor missed required turnaround times. The figures reveal a program that failed far more than sporadically. Its approval-to-denial ratio had been fundamentally skewed since the program began.
Such failures cut across several vendors and parts of the program. Update logs showed that technology suppliers and the Medicare Administrative Contractors failed to coordinate, disrupting mandatory workflows so that providers' approval requests were sorted into wrong categories. Outages made matters worse, as did numerous grievances from providers regarding slow responses and inadequate outreach by Innovaccer, the vendor handling Ohio requests. A single approval sat without a response for 83 days. This incident illustrates precisely what exception handling should stop: a marked submission that automated systems left hanging without ever getting to staff while action was still possible.
Oversight of the program remains ongoing. A 46 to 50 Senate tally in July 2026 blocked efforts to repeal it, leaving its shortcomings closely watched. Officials will continue treating this episode as a reference point while determining how to assign responsibility for results generated by AI decision pipelines across health and insurance settings.
WISeR is a case study of the claim developed across the preceding two sections. A provider's request that ends up misclassified represents a breakdown in validation, the sort that duplicate checks and reference-data verification exist to prevent. A request left waiting 83 days for an answer reflects a breakdown in exception handling, the sort that well-designed routing and priority controls exist to stop. Miscommunication between vendors and contractors signals a breakdown in pipeline integration, the sort that a shared data model exists to prevent. All three occurred within one program simultaneously. These three functions collapse as a set when one is built weakly, since each relies on the other two to work.
The compounding error problem that confidence thresholds alone cannot solve
Even with rigorous checks and thoughtfully designed error management, pipelines retain a vulnerability that no confidence threshold can fully eliminate. Since AI generates a fresh prediction with each action, individual stages within a longer sequence may appear sound even as overall reliability deteriorates. Strong certainty ratings during extraction, validation, and routing never combine to guarantee equally reliable final results. Because doubt accumulates sequentially, labeling each phase "probably correct" differs from calling the outcome "probably correct" once a case is fully resolved.
Bringing in a Human to check the work is the usual fix for such a risk, yet it introduces its own failure that confidence thresholds cannot prevent. This automatic habit transforms what should protect the process into its weakest point. Once oversight ceases to function, poorly designed pipelines let mistakes pass unchallenged while wearing the mask of authorized choices.
This technical failure also directly undermines confidence in insurance. Insured customers are anxious that AI-driven claim choices will sideline human judgment, a concern the evidence supports; compounding error gives their discomfort with automation a specific engineering foundation. When a policyholder fears their claim is passing through unseen, that concern is grounded in how the system may actually operate. In a sufficiently extended workflow, many reasonable-seeming outputs can accumulate until the system behaves that way, especially if validation and exception handling do not surface failures that confidence scores alone miss.