Human-in-the-Loop Annotation Quality Control for Document AI
Layered human checks catch silent model failures that confidence scores alone cannot detect.
Ingrid Halvorsen
Senior Correspondent, Document Intelligence
Ingrid spent nine years building document ingestion systems for insurance and legal-tech firms before moving into reporting. She covers parsing accuracy and extraction evaluation with a bias toward what holds up on real corpora rather than benchmark suites.
5 stories
Layered human checks catch silent model failures that confidence scores alone cannot detect.
Consistency in LLM judges doesn't guarantee they measure what actually matters.
Removing duplicates cuts training tokens by 13-41% while preventing memorization.
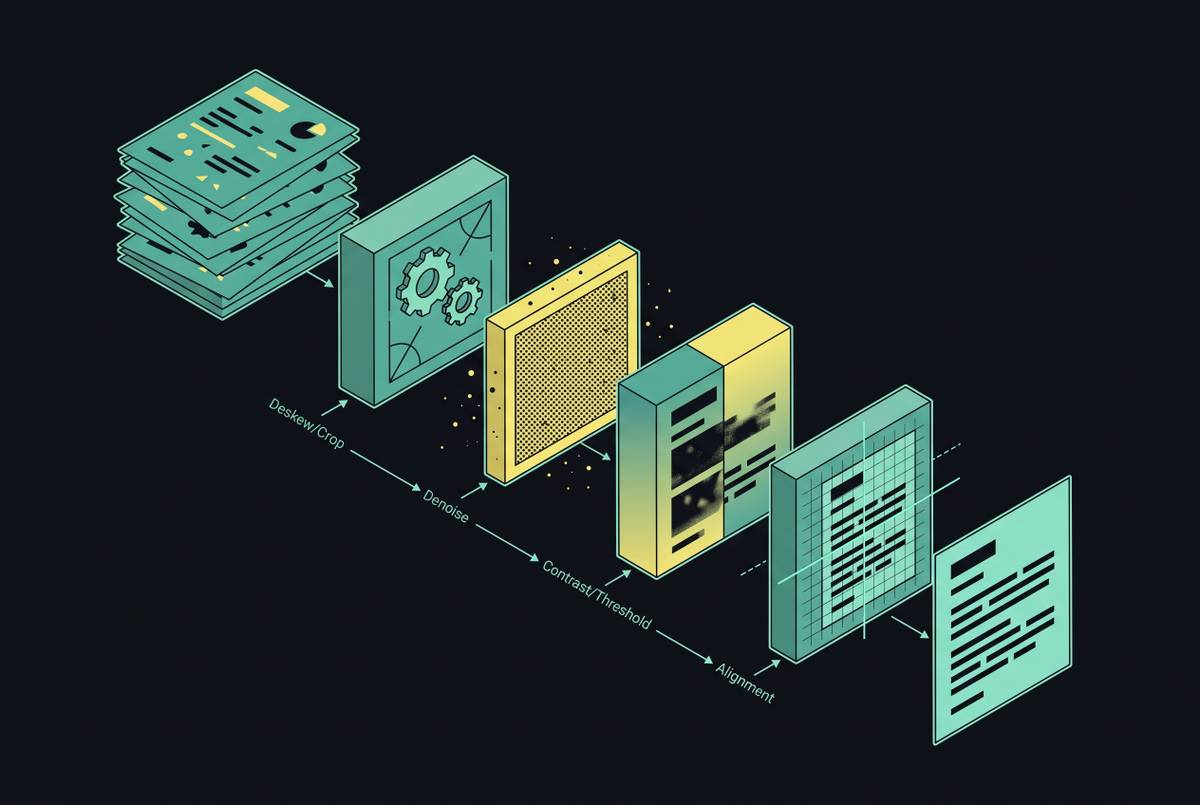
Sequence matters: preprocessing steps in the wrong order leave OCR stuck between broken and working.
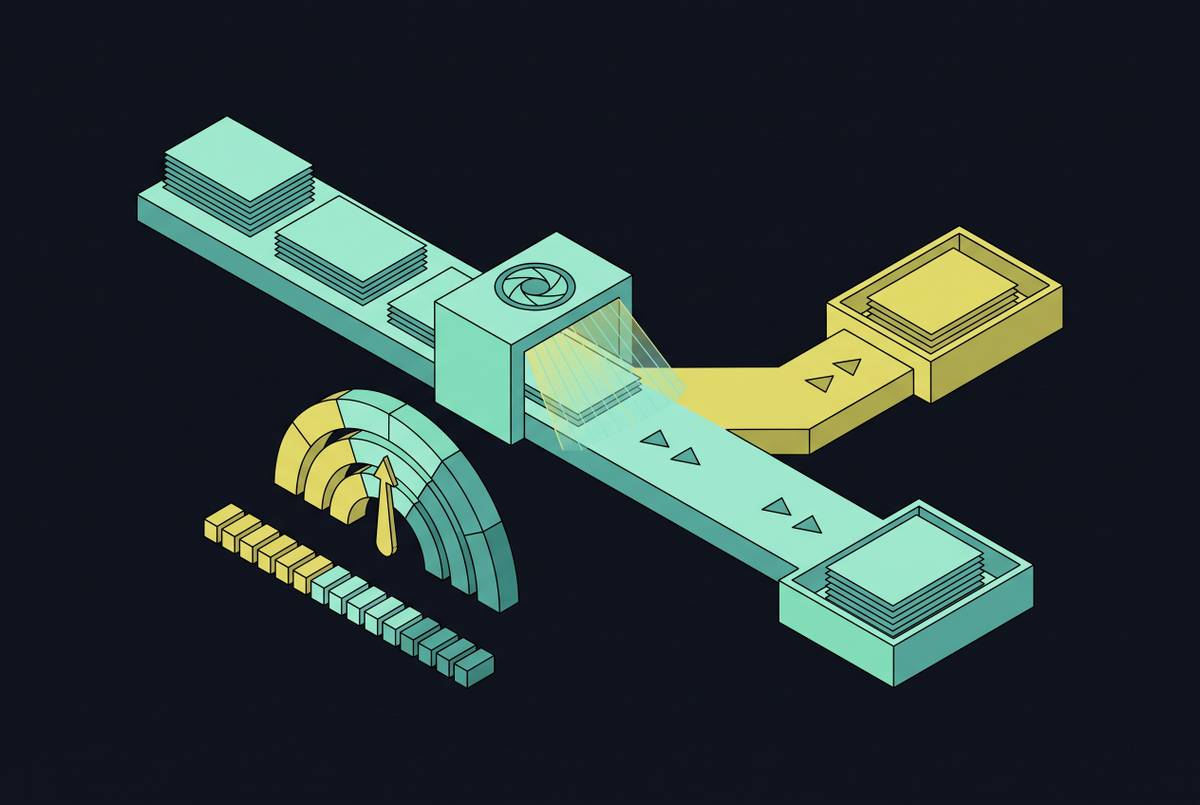
Confidence scores route OCR extractions, but only if thresholds match the document type and risk.